Tool-Selection LLM — LoRA Fine-tune on xLAM
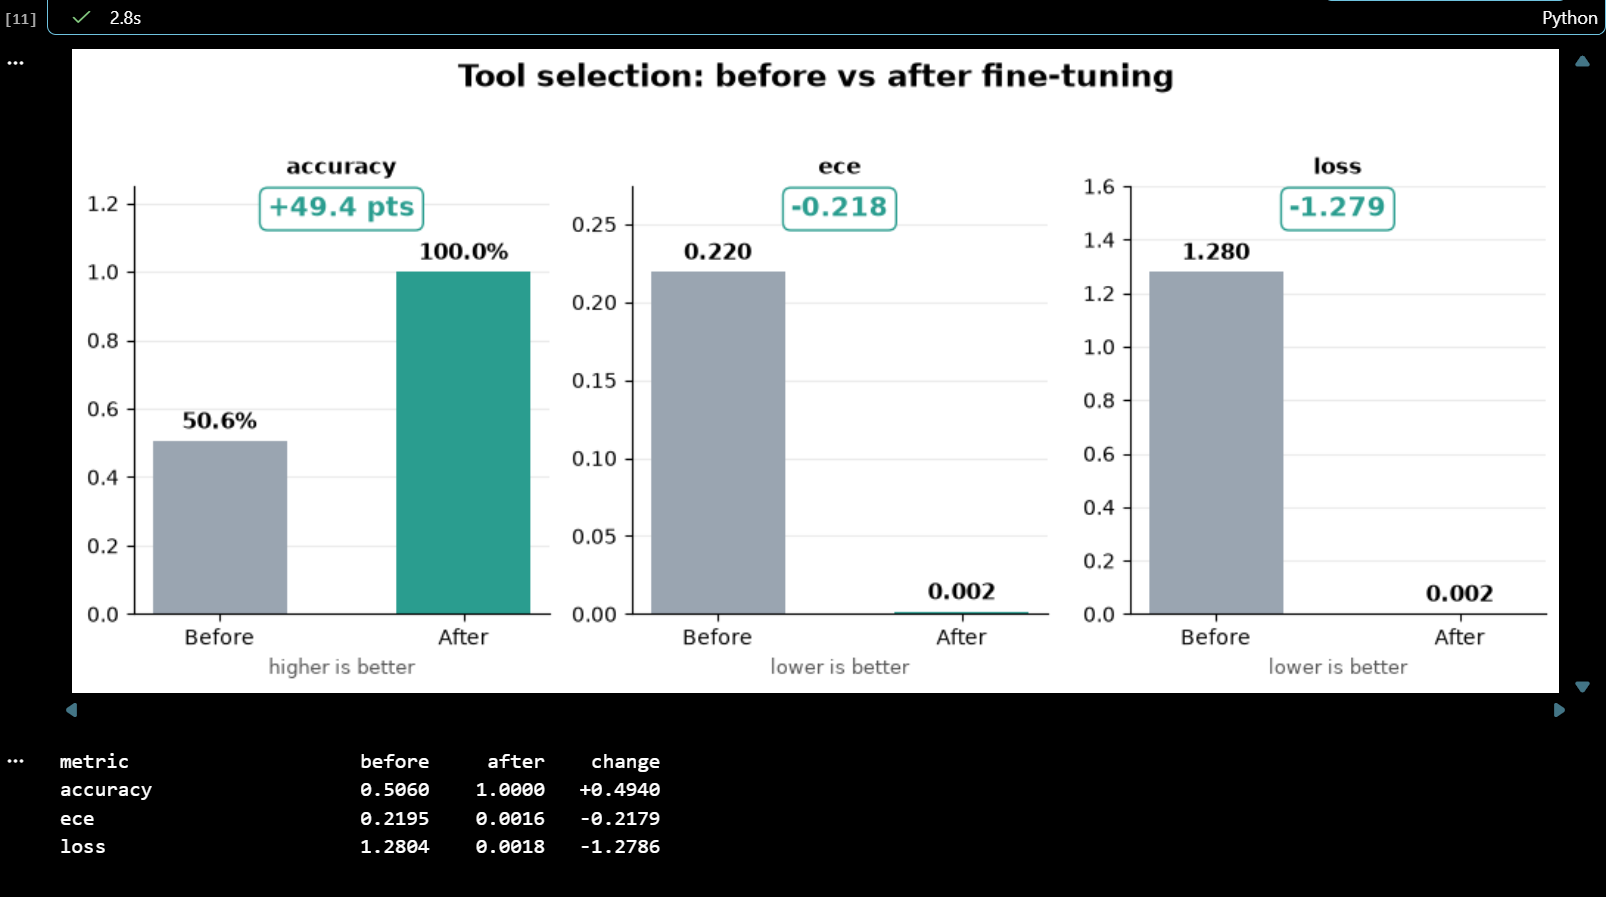
Teaching a small LLM to pick the right tool/API for an agent — and say how confident it is. LoRA-tuned Qwen3.5-2B with Unsloth on xLAM function-calling data: 50.6% → 100% accuracy, ECE 0.220 → 0.002.
role: Solo builder
Goal
Given a user request and 3–5 candidate tools, a small LLM should pick the right tool and output a probability per tool. This is the "which API should the agent call?" step that sits in front of any agent or MCP setup.
"Can you list the music genres available?" — tools:
get_genres,hot_100_songs,songs_v2_get_details,fetch_track_details→get_genres
Data
- xLAM function-calling 60k (Salesforce; ungated mirror on Hugging Face)
- Kept rows with exactly one correct tool and 3–5 candidates, removed duplicate requests, shuffled tool order so the answer isn't always first
- 13,821 train / 1,000 test rows available; quick run uses 5,000 train / 500 test, 2 epochs
Results (one run, RTX 5050 8 GB)
| Metric | Before | After |
|---|---|---|
| Accuracy | 50.6% | 100% |
| ECE (lower is better) | 0.220 | 0.002 |
| Loss | 1.280 | 0.002 |
Calibration matters here: an agent router needs "80% confident" to actually mean right 80% of the time, so it can fall back or ask for clarification when unsure.
Honest caveat & next step
The test split is random, so the same tools appear in train and test — 100% shows the model learned this distribution, not yet that it generalises to unseen tools. Next: evaluate on tools held out from training.
Agentic AI Chatbot Platform
Production multi-agent assistant for cybersecurity & case management — a router agent dispatching to five specialist agents across hybrid RAG, text-to-SQL and action execution, on self-hosted vLLM.
RedForge — AI Red-teaming & GenAI Eval Platform
Target-agnostic platform that attacks any LLM chatbot with 200+ OWASP-LLM-Top-10 test cases and an adversarial mutation engine. Built on personal time, adopted as a company product.
3B Tokens/Day Vision-LLM Inference on One GPU
Scaled self-hosted vision-LLM screenshot analysis to 3 billion input and 50 million output tokens per day on a single 96GB GPU — no third-party API spend.