DocuMind AI — Grounded Multimodal Document Q&A at Scale
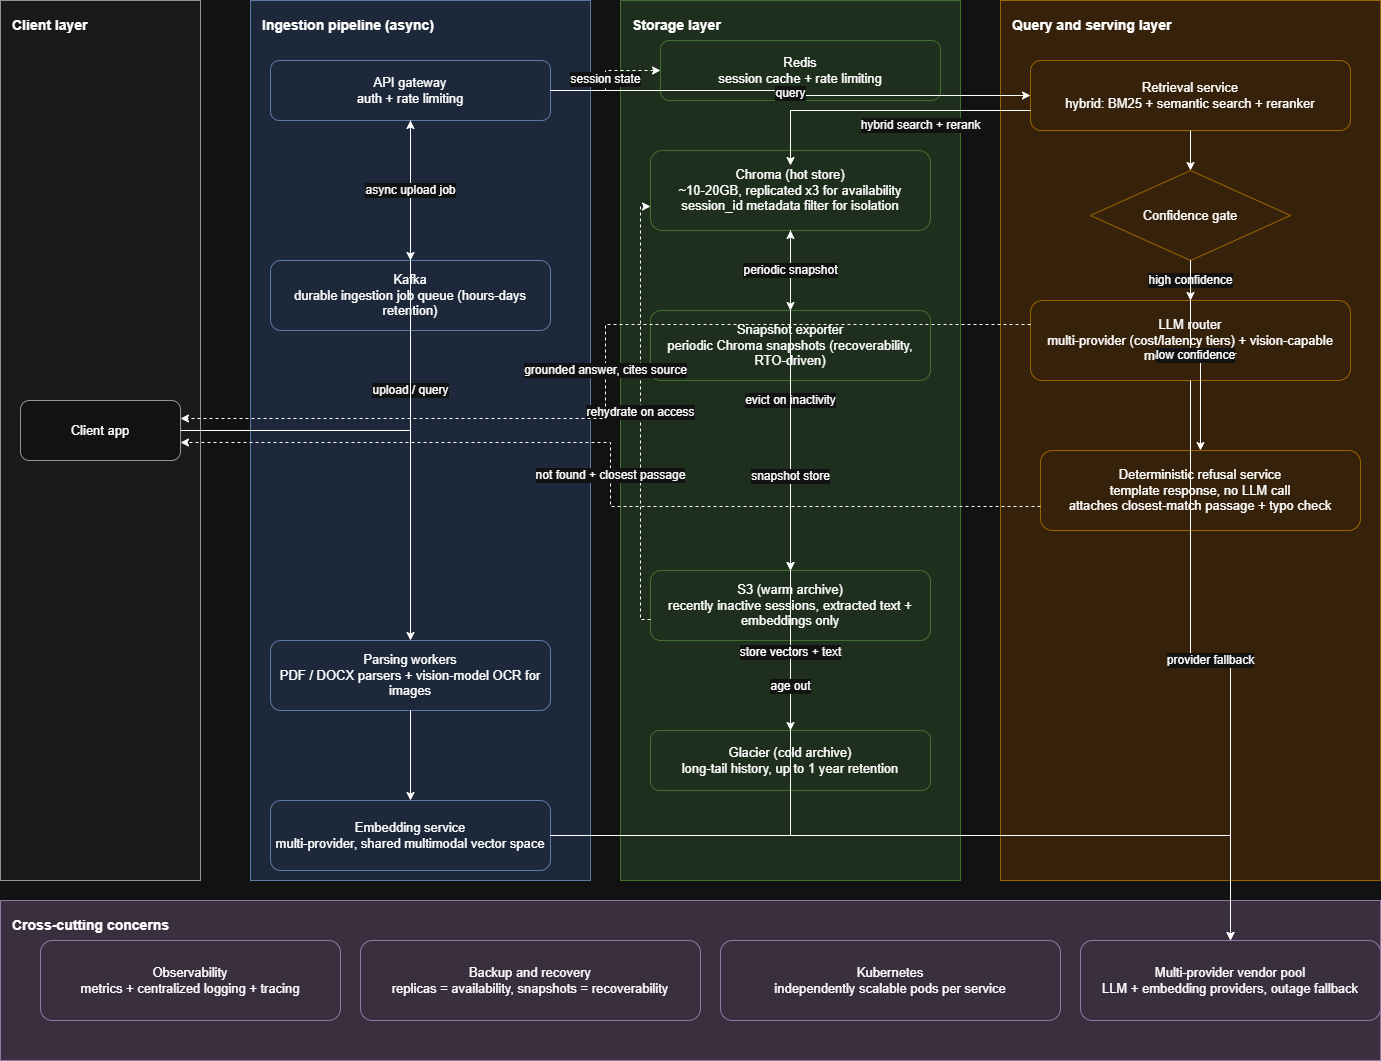
System design for a 1M-user document Q&A product: async multimodal ingestion, hybrid retrieval, a deterministic confidence gate that refuses instead of hallucinating, and hot/warm/cold session tiering.
role: System designer
Problem
~1M users upload mixed documents per session (50–60 page PDFs, Word docs, scanned payslips/bills) and ask questions that must be answered strictly from that content — "not found" is preferred over a wrong answer. Sessions resume up to a year later.
Architecture
Key decisions
- Refusal is code, not a prompt. Below a retrieval-confidence threshold the LLM is skipped entirely and a deterministic "not found" + clearly labelled closest passage is returned — the accuracy guarantee doesn't depend on the model behaving.
- Size hot storage by concurrency, not headcount. An early "5 warm sessions per user" estimate gave ~10.5 TB; sizing by 5–10k concurrent sessions × ~2.1 MB gives ~10.5–21 GB — a 500–1000× correction.
- Retention policy — raw files discarded ~30 days after parsing; only text + embeddings kept → ~928 TB/yr instead of ~6.2 PB/yr.
- Layout-aware multimodal ingestion for financial documents, with a shared multimodal embedding space so text queries retrieve image-derived chunks.
- Replicas for availability, snapshots for recoverability — rebuilding the index is cheap in dollars but expensive in recovery time.
Capacity (per session ≈ 152 pages ≈ 99k tokens)
| Metric | Value |
|---|---|
| Chunks / session | ~283 (400-token chunks, 50 overlap) |
| Embeddings / session | ~1.7 MB (1536-dim) |
| Sessions / year | ~442M across 3 user cohorts |
What I'd revisit
Confidence-threshold calibration needs an offline eval set of answerable vs. unanswerable questions; cold storage needs a deep-archive/deletion policy agreed with product & legal.
Agentic AI Chatbot Platform
Production multi-agent assistant for cybersecurity & case management — a router agent dispatching to five specialist agents across hybrid RAG, text-to-SQL and action execution, on self-hosted vLLM.
3B Tokens/Day Vision-LLM Inference on One GPU
Scaled self-hosted vision-LLM screenshot analysis to 3 billion input and 50 million output tokens per day on a single 96GB GPU — no third-party API spend.
Self-learning Few-shot Text-to-SQL
A retrieval-driven few-shot engine that harvests successful queries as exemplars and injects them dynamically — lifting text-to-SQL accuracy from 60% to 95% with no retraining.